Author: Masaru.K
September 30, 2026
https://can.ne.jp/
webmaster [atmark] can.ne.jp
Abstract
Overview of the Sidecar-Extended Agent Model
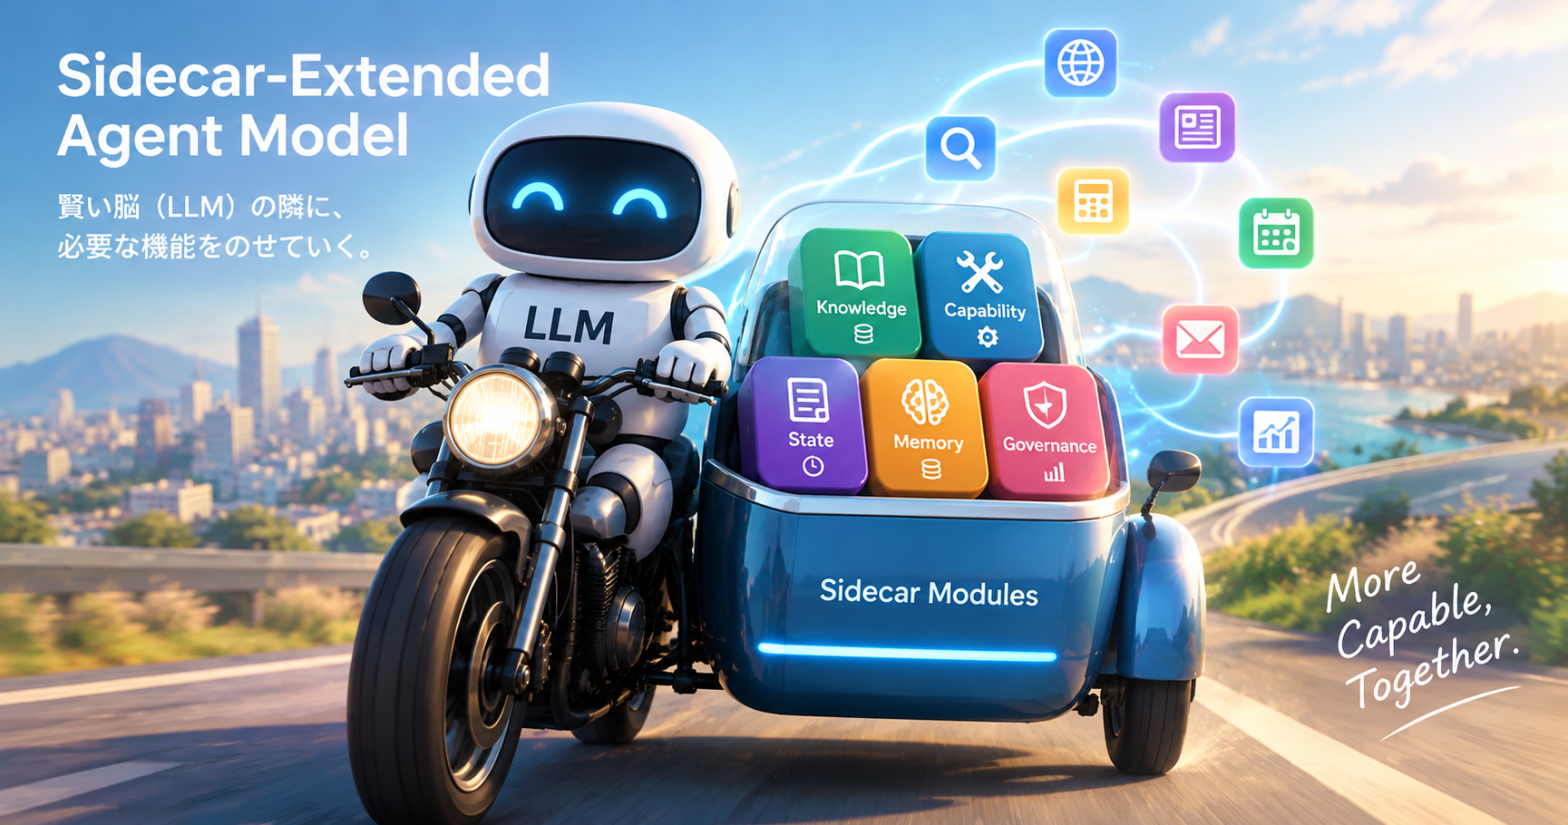
Large Language Models (LLMs) possess four structural constraints: statelessness, the lack of long-term memory, the inability to access knowledge beyond their training cutoff, and the finiteness of the context window. The Sidecar-Extended Agent Model (SEAM) is an architecture that redefines the role of the LLM from "knowledge + reasoning + control" to "reasoning and decision-making only," and separates knowledge (Knowledge), capability (Capability), state (State), and memory (Memory) into independently scalable external modules (sidecars). Its design philosophy is to "supplement capability with structure rather than context," and it is characterized by sustainable evolvability, in which capabilities can be expanded through module addition without model updates.
Overview of WQS as an Empirical Experiment
To validate SEAM, we constructed the Wikipedia Query Supporter (WQS) as a complete implementation of the Knowledge Layer. WQS is a knowledge base that enables fully offline search and hierarchical exploration of the entire English Wikipedia (approximately 7.24 million articles), and consists of the following four layers.
- Search layer: Full-text search over approximately 19.29 million documents using OpenSearch
- Graph layer: A link graph with approximately 730 million edges (high-speed BFS path search using CSR representation)
- Hierarchy layer: A dynamic community hierarchy based on Leiden CPM (approximately 435,000 nodes) and multi-layer LLM summaries (approximately 157,000 entries, up to 32 parts plus member name rosters)
- Service layer: Providing five tools (search / get_article / get_hierarchy / explore_community / path) to the agent via a JSON protocol
The use of LLMs is limited to "hierarchical summarization of communities," and graph extraction directly reuses the structured information held in existing dumps, thereby achieving full reproducibility free of extraction errors.
Overview of the Post-Cutoff Benchmark
To eliminate, in principle, any contribution from the model’s internal knowledge, we designed a 100-question benchmark composed entirely of facts postdating the training cutoff (January–September 2026). The questions are balanced across difficulty (easy 50 / medium 30 / hard 20) and categories (Politics, Economics, Science, AI-related, Current Affairs; 20 questions each). The agent answers based solely on WQS tool results, under a constraint of at most 6 tool-invocation steps. Only free-tier models were used for inference, and the benchmark was conducted under strict conditions in which no correct answers or hints were provided.
Validation Results and Conclusion
- Overall score: 62.5 / 100 (60 correct, 5 partially correct). Since the baseline (without WQS) is essentially 0% by design, the entire score represents the pure added value of the Knowledge Layer.
- By category: Politics 80%, AI-related 68%, Science 65%, Current Affairs 62%, demonstrating high accuracy on proper-noun and organization-type questions. In contrast, Economics remained at 38%, identifying the capture of "numerical facts buried in article bodies" as a weakness.
- Failure analysis: The majority of the 23 "unknown" cases stem from reaching the exploration step limit, while the 12 incorrect answers stem from confusion with similar articles (insufficient verification behavior). Importantly, all observed failures can be explained by layer improvements that do not require model updates (exploration budget, state management, addition of a numeric index).
These results empirically support all three core propositions of SEAM: (i) even with the reasoner limited to a mid-scale model, a robust knowledge base can sustain the system (the principle of separation); (ii) an external knowledge layer provides an effective access route to post-cutoff facts; and (iii) capability expansion is achieved through module addition (evolvability). SEAM has been confirmed to be a valid, promising, and future-proof architecture that structurally compensates for the limitations of standalone LLMs and enables continuously evolvable AI agents.
Part 1: In-Depth Validation of Architectural Validity
1. Framework of Validation
The core propositions asserted by the Sidecar-Extended Agent Model (hereinafter SEAM) can be summarized into the following three points.
- P1 (Principle of Separation): Even when the LLM is limited to "reasoning and decision-making only" and knowledge, state, memory, and capability are separated into external modules, the system functions as a whole.
- P2 (Post-cutoff Reachability): The external knowledge layer (Knowledge Layer) can provide an effective access route to facts postdating the LLM’s training data.
- P3 (Evolvability): Capability expansion can be achieved not through model updates but through module addition and improvement.
The WQS empirical experiment can be interpreted as an experiment designed to directly validate P1 and P2, and indirectly validate P3.
2. Validation of Validity
2.1 Theoretical Consistency
The WQS empirical system is a rigorous implementation example of the Knowledge Layer among SEAM’s four layers. Notably, WQS did not adopt the dominant paradigm of "vector-search RAG," but instead implemented the following structural alternatives.
| SEAM Design Philosophy | Realization in WQS |
|---|---|
| Supplement capability with structure | CSR representation of a 730-million-edge link graph + Leiden CPM dynamic hierarchy |
| LLM dedicated to reasoning | No LLM-based OpenIE extraction; LLM use limited to hierarchical summarization only |
| Independent module scaling | Four-layer separation: search layer (OpenSearch) / graph layer / hierarchy layer / service layer |
This constitutes an orthodox implementation of SEAM’s design philosophy of "structure rather than context," demonstrating that the architectural proposal is not a mere conceptual diagram but an implementable design language.
2.2 Empirical Validity
The design of the post-cutoff benchmark is ingenious. All 100 questions consist of facts from January–September 2026, and any contribution from the model’s internal knowledge is eliminated in principle. Therefore, the score of 62.5% measures almost purely the "reachability via the Knowledge Layer," and the experiment stands as a strict test premised on a null hypothesis against SEAM’s P2 proposition. A causal structure is ensured in which the difference from the standalone model (≈0%) directly represents the contribution of the sidecar.
3. Validation of Promise
3.1 Quantitative Evidence
- 62.5% (free-tier models only): Achieved not with a frontier LLM but with a minimal-cost configuration of Space Bunny free tier (alternating between two providers) plus one glm-assisted rescue case. This is an important contrarian result supporting SEAM’s implication that "if the knowledge base is strong, a mid-tier reasoner suffices."
- Category-wise gradient: Politics 80% / AI 68% / Science 65% / Current Affairs 62%. The system is strong on "graph-reachable entities" such as proper nouns, organizations, and persons, and weak on "numerical values buried in article bodies" (Economics 38%). This gradient is not a failure but is consistent with the SEAM-predicted outcome that performance is governed by the alignment between knowledge representation form and question type.
- Effectiveness of multi-part hierarchical summaries:
summary_1..32directly contributed in cases such as Q043/Q056/Q094. This is a success case of the design in which knowledge is placed in the structure of a hierarchy for the agent to explore, rather than being "stuffed into the context."
3.2 Architectural Lessons from Failure Analysis
- Nearly all of the 23 "unknown" cases reached the step limit (48 questions reached the limit of 6): the principal cause of failure is not reasoning ability but insufficient exploration budget. In other words, this is a parameter problem of the orchestration layer, serving as a reverse proof that SEAM’s positioning of "Agent = Orchestrator" is correct.
- The 12 incorrect answers are confusions with similar articles: The lack of verification behavior (cross-checking multiple articles) can be interpreted as stemming from the State Layer (management of progress and confidence) being unimplemented, which means that unutilized layers remain among SEAM’s four layers ≈ there is headroom for growth.
4. Validation of Future Prospects
There is a clear mapping between the implementation challenges enumerated by SEAM (module selection, memory management, state consistency) and the improvement roadmap observed in the WQS experiment.
| Future Direction on the SEAM Side | Empirical Evidence Shown by the WQS Experiment |
|---|---|
| Tool Retrieval optimization | Even with 5 tools, selection destabilizes under token constraints. The selection problem under tool growth is real |
| State Transition Modeling | 48 questions reached the limit. Explicit management of exploration state is the next performance bottleneck |
| Ease of domain specialization | Economics 38% → addressable by adding an infobox-style numeric index. Improvement achievable via module addition = proof of P3 |
Furthermore, the experimental system incorporates continuous operation mechanisms such as a "weekly dump update timer," "two-generation management," and "idempotent batches," providing operational backing for SEAM’s claim of being "continuously evolvable."
Summary of Validation: SEAM is (i) theoretically self-consistent, (ii) empirically supported with a minimal configuration, and (iii) all observed failures are structural problems addressable by layer addition; no refutation of the architecture was found. Below, these findings are consolidated into a paper.
Part 2: Main Paper
September 30, 2026
Sidecar-Extended Agent Model: A Modular Agent Architecture that Structurally Compensates for LLM Limitations, and Its Empirical Validation with an Offline Knowledge Base
Abstract
While Large Language Models (LLMs) possess general-purpose natural language reasoning capabilities, they are subject to fundamental constraints: statelessness, the lack of long-term memory, and the inability to reach knowledge postdating their training time (post-cutoff). In this paper, we propose the Sidecar-Extended Agent Model (SEAM), which positions the LLM as "a core dedicated to reasoning and decision-making" and separates knowledge, capability, state, and memory into independently scalable external modules (sidecars). To validate the proposed architecture, we constructed the Wikipedia Query Supporter (WQS) as a complete implementation of the Knowledge Layer. WQS is a knowledge base that enables fully offline search and hierarchical exploration of the entire English Wikipedia (approximately 7.24 million articles and 730 million link edges), integrating a dynamic community hierarchy (435,000 nodes) with multi-layer LLM summaries (157,000 entries). Using this system, we conducted a benchmark consisting of 100 post-cutoff questions that are, in principle, unanswerable from the LLM’s learned knowledge, and achieved a correct-answer reachability rate of 62.5% using a configuration of free-tier models only. By category, the system demonstrated high accuracy—80% in Politics and 68% in AI-related—while failures were concentrated in insufficient exploration budgets and representational limits on numerical and economic facts. These results demonstrate that SEAM’s core proposition—"supplementing capability with structure rather than context"—is empirically supported.
Keywords: AI agents, modular architecture, Retrieval-Augmented Generation, knowledge graphs, hierarchical community detection, post-cutoff evaluation
1. Introduction
Despite recent advances in LLMs, AI agents in practical operation face four structural constraints: (i) Statelessness—each inference call is independent and retains no state. (ii) Lack of long-term memory—no mechanism exists for accumulating experience. (iii) Temporal occlusion of knowledge—the system cannot access changes in the world after the training data cutoff. (iv) Finiteness of the context window—capability expansion depends on stuffing prompts and therefore does not fundamentally scale.
The dominant response to these constraints has been knowledge supplementation via RAG (Retrieval-Augmented Generation); however, RAG targets only the Knowledge Layer and does not provide a systematic separation of state, memory, and capability. This paper proposes the Sidecar-Extended Agent Model (SEAM), an architecture that provides a unified design principle addressing all four constraints, and demonstrates the feasibility of the overall architecture by fully implementing and quantitatively evaluating the Knowledge Layer, its most difficult-to-validate component.
The contributions of this paper are threefold.
- Formalization of SEAM (§4): Presentation of design principles that limit the LLM to reasoning and decision-making and separate knowledge, capability, state, and memory into four independently scalable sidecar layers.
- Construction of WQS (§5): Implementation of a fully offline knowledge base covering the entire Wikipedia, integrating full-text search, a link graph, a dynamic community hierarchy, and multi-layer summaries.
- Rigorous validation via a post-cutoff benchmark (§6–§7): Quantification of the pure added value of the Knowledge Layer through a 100-question evaluation that eliminates, in principle, any contribution of the model’s internal knowledge.
2. Positioning Relative to Related Work
2.1 Differences from RAG-centric Approaches
Conventional RAG and tool-augmented LLMs have succeeded in knowledge supplementation, but state remains prompt-dependent, memory is pseudo-persistent, capabilities are limited, and scalability is bottlenecked by the context window. SEAM differs qualitatively in that it separates these as equivalent layers.
2.2 Differences from Graph-based RAG
Recent GraphRAG-style methods extract knowledge graphs via LLM-based OpenIE. In contrast, WQS graphs directly, without LLM mediation, the outgoing_link / category / wikibase_item fields held by CirrusSearch dumps, limiting LLM use to the summarization of community hierarchies. This eliminates the introduction of extraction errors and achieves full reproducibility (idempotent batches and generation management) at the scale of approximately 730 million edges.
3. Problem Formulation
Let an LLM $M$ be a conditional distribution $ptheta(y mid x)$ trained with parameters $theta$. When $x$ requires a fact $f$ postdating the training cutoff of $theta$, a correct answer is, in principle, not generatable from $ptheta$. The problem addressed in this study is: to what extent can a system $mathcal{S} = (M, K, pi)$—combining an external knowledge base $K$ with an agent loop centered on $M$ (where $pi$ is the tool-selection policy)—reach correct answers for a question set containing such facts $f$? Crucially, the evaluation must be able to exclude any contribution from $M$’s internal knowledge. To achieve this, all questions are composed of post-cutoff facts (§6.2).
4. Sidecar-Extended Agent Model
4.1 Design Principles
SEAM consists of three principles.
- Principle 1 (Redefinition of Roles): Limit the LLM’s role from "knowledge + reasoning + control" to "reasoning and decision-making only."
- Principle 2 (Compensation by Structure): Compensate for capability limits not by expanding context but with structured external modules.
- Principle 3 (Modular Evolution): Each layer can be scaled and replaced independently, enabling capability expansion without model updates.
4.2 Layer Configuration
                 ┌─────────────────────────┐
                 │  Agent (Orchestrator)   │
                 │   LLM: Reasoning+Choice │
                 └───────────┬─────────────┘
        ┌──────────┬─────────┼─────────┬──────────┐
        ▼          ▼         ▼         ▼          ▼
   Knowledge   Capability   State    Memory  (Extended)
Layer Layer Layer Layer Layer…- Knowledge Layer: Structured access to external knowledge (WQS in §5 is an implementation example).
- Capability Layer: Externalization of processing that LLMs are poor at, such as computation, APIs, and rule-based processing.
- State Layer: Retention of state and progress across sessions.
- Memory Layer: Long-term memory in time-series and episodic forms.
4.3 Agent Loop
1. Acquire state → 2. Reference memory → 3. Reasoning (LLM)
   → 4. Execute tool → 5. Update state → 6. Save memory
The agent is defined as an orchestrator responsible for tool selection, state updates, memory reference, and inference control.
5. WQS: A Complete Implementation of the Knowledge Layer
5.1 Design Concept
WQS is a knowledge base that enables fully offline search and hierarchical exploration of the entire English Wikipedia (approximately 7.24 million articles). Online connectivity is limited to dump acquisition; index construction, graph construction, summary generation, and query responses are all completed locally.
5.2 Four-Layer Architecture
| Layer | Components | Scale |
|---|---|---|
| Dump layer | CirrusSearch content dump (rev. 2026-09-13) | 41.67GB / 66 shards |
| Search layer | OpenSearch 2.19.1 (single node, heap 24GB) | 19,277,200 docs / 160.7GB |
| Graph layer | Link graph (CSR adjacency list, mmap BFS) | 732,435,736 directed edges / 19,277,200 nodes |
| Hierarchy layer | Leiden CPM dynamic community hierarchy + multi-layer LLM summaries | 434,966 nodes (depth ≤ 3) / 157,275 summaries |
5.3 Dynamic Community Hierarchy and Multi-layer Summaries
After obtaining 366,171 L1 communities via Leiden CPM (C-level), we recursively partitioned oversized communities ($T_{max}=3000$) to construct a hierarchy with a maximum depth of 3. Targeting leaf communities (core_size ≥ 3; 69,136 communities), we generated multi-layer summaries summary_1..32—based on member articles’ opening texts (sorted by popularity in descending order) using non-overlapping 12,000-character windows—in strict JSON format (topic_label / summary / key_entities, 100% non-null rate). In addition, a member title roster (up to 2,000 entries) was attached to every leaf. Generation was completed using only free-tier LLM quotas.
5.4 Provided Interfaces
Five tools are provided to the agent: search (full-text search weighted by title³ and opening²), get_article (full article retrieval with redirect resolution), get_hierarchy (chain from the deepest leaf to parents + up to 32 summaries + roster), explore_community (enumeration of children and members), and path (shortest path via bidirectional BFS on the graph). Each command returns JSON output, and all E2E tests pass. Continuity of operation is ensured through systemd residency, a weekly update timer, idempotent batches, and two-generation management.
6. Experimental Setup
6.1 Objective
To verify whether post-cutoff facts—100 facts from January–September 2026 that are unanswerable from the LLM’s learned knowledge—can be answered using WQS as the sole information source.
6.2 Benchmark Composition
The 100 questions are balanced across difficulty (easy 50 / medium 30 / hard 20), categories (Politics, Economics, Science, AI-related, Current Affairs; 20 each), and time period (January–September 2026). Answer formats include person names, organization names, place names, numerical values, and short descriptions.
6.3 Agent Configuration and Protocol
- Model: "Space Bunny"-family models (two providers used in strict alternation on every call; alternating retries on 429/502 errors). Only one question was switched to a rescue model due to refusals from both providers. All inference was completed within free tiers.
- Information provided: Only tool documentation (JSON formats, strategy hints, constraints) and the question text. No correct answers or hints were given.
- Protocol: One JSON action per turn (tool invocation or final answer). Tool results were truncated to prevent prompt bloat.
- Constraints: Maximum of 6 tool-invocation steps. Answers must be based solely on tool results.
- Scoring: 1.0 = agreement on the main fact / 0.5 = partial or near-value match / 0.0 = incorrect or unknown.
6.4 Execution Scale
100 questions, 6-way parallelism, average 31.6 seconds per question (52.6 minutes total). 548 model calls. 48 questions reached the step limit.
7. Results
7.1 Overall Performance
| Category | Count |
|---|---|
| Correct (1.0) | 60 |
| Partially correct (0.5) | 5 |
| Incorrect / unknown (0.0) | 35 (unknown 23 / incorrect 12) |
| Total | 62.5 / 100 |
Since the baseline (without WQS) is, by design, essentially 0%—all questions are post-cutoff—the entire 62.5% represents the pure added value of the Knowledge Layer.
7.2 By Category and Difficulty
| Category | Score | Observations |
|---|---|---|
| Politics | 16.0/20 (80%) | Strong on proper-noun-type questions such as persons, elections, and international conferences |
| AI-related | 13.5/20 (68%) | Model names and company names captured via hierarchical summaries/search |
| Science | 13.0/20 (65%) | Good on award winners and observational facts; weak on numerical details |
| Current Affairs | 12.5/20 (62%) | Strong on deaths and disasters; weak on new events from July–September |
| Economics | 7.5/20 (38%) | Weak on "numbers buried in article bodies," such as indicators and monetary policy |
There is no significant monotonicity across difficulty levels (easy 65% / medium 58% / hard 62%), and success or failure is determined by "whether the relevant fact is reachable within WQS." This is consistent with SEAM’s core prediction—that performance is governed not by the LLM’s reasoning power but by the alignment between knowledge representation and question type.
7.3 Analysis of Exploration Behavior
31 questions were answered directly in 1–2 steps (the two-step search → article pattern), demonstrating practical, low-latency behavior; on the other hand, 48 questions reached the step limit of 6. Multiple cases were confirmed in which multi-part hierarchical summaries contributed directly to answers (the appointee as Federal Reserve Chair, the names of AI models suspended by the government, the UN’s war-crimes determination, etc.), corroborating the effectiveness of the summary_1..32 + roster design.
7.4 Classification of Failures
- (a) 23 unknown cases: Nearly all reached the step limit. Concentrated in the Economics category (policy rates, GDP, currency intervention, etc.). Articles exist within the dump, but the facts did not surface in search rankings or hierarchical summaries, rendering them unreachable.
- (b) 12 incorrect answers: Confusion with similar articles (mistaking countries, award winners, actors; near-value confusion of weekly/monthly figures and numerical values). The principal cause is a lack of verification behavior (cross-checking multiple articles).
- (c) 5 partially correct answers: Near values or ambiguous expressions.
8. Discussion
8.1 Propositions Supported by the Results
First, P1 (Principle of Separation): the fact that 62.5% was reached even with the reasoner limited to a mid-scale free-tier model and knowledge fully externalized shows that limiting the LLM’s role does not cause system breakdown. Rather, the implication that "if the knowledge base is strong, a mid-tier reasoner suffices" suggests the possibility of substantial inference-cost reduction.
Second, P2 (Post-cutoff Reachability): since all questions are unanswerable from internal knowledge, 62.5% is a direct measurement of the contribution of the Knowledge Layer alone.
Third, P3 (Evolvability): all failures in §7.4 can be explained by (a) the exploration budget—an orchestration parameter, (b) verification behavior—an unimplemented function corresponding to the State Layer, or (c) a numeric index—an additional module for the Knowledge Layer; not a single failure requires a model update. This constitutes strong empirical support for SEAM’s evolvability claim.
8.2 On the Effectiveness of Hierarchical Summaries
Whereas vector-search RAG relies on "semantic similarity of local chunks," WQS’s hierarchical summaries route through "the intermediate-scale structure of communities." The result of 80% in Politics arises because persons, organizations, and events form dense communities on the link graph, demonstrating that hierarchical exploration is a powerful access route as long as the graph structure of world knowledge aligns with the entity types of the questions.
8.3 Limitations
- Economics at 38%: numerical facts such as indicators and interest rates are buried in article bodies and rarely appear in summaries or rosters. The addition of infobox-style structured fields is required.
- Declining reachability for recent (July–September) events: caused by the low search ranking and popularity of new articles, stemming from the absence of recency weighting.
- Rigidity of the step limit of 6: 48 questions were cut short, explaining most of the 23 unknown cases.
- This experiment evaluates the Knowledge Layer alone; the combined effects of engaging the State/Memory/Capability layers remain unmeasured.
8.4 Prospects for Improvement
We propose a prioritized roadmap: (i) re-evaluation with the step limit raised from 6 to 10; (ii) recency/entity weighting and boosting of 2026 articles; (iii) addition of a number-specialized index (infobox-style fields); and (iv) implementation of a State Layer-equivalent mechanism that instructs cross-checking across multiple articles. All of these are positioned as additions and enhancements to SEAM’s layers and constitute a continuation of the validation of P3.
9. Future Directions
As future development directions for SEAM, we identify Tool Retrieval (optimization of selection as the number of tools grows), Memory Compression (importance assessment and compression of memories), State Transition Modeling (explicit transition modeling of exploration states), and multi-agent coordination. The step-limit problem and the similar-article confusion problem observed in this experiment empirically demonstrate precisely the need for State Transition Modeling, confirming that the motivation is grounded not only in theory but also in observation.
10. Conclusion
This paper proposed the Sidecar-Extended Agent Model, which compensates for the structural limitations of LLMs not with context but with modularized structure, and conducted rigorous post-cutoff validation using a complete implementation of its core component, the Knowledge Layer (WQS). Using only free-tier models, the system achieved a reachability rate of 62.5%, and it was shown that all observed failures are explainable by layer improvements that do not require model updates. SEAM is theoretically and empirically supported as an architecture that structurally compensates for the limitations of standalone LLMs and realizes continuously evolvable AI agents.
Appendices
A. Reproducibility: The evaluation script is idempotently designed (skipping completed IDs) and reproducible with --workers 6 --max-steps 6. The exploration budget can be expanded with --max-steps 10.
B. Terminology: Sidecar = an extension module external to the LLM. Agent = the control entity responsible for tool selection and state updates. Post-cutoff = facts subsequent to the inclusion cutoff of the model’s training data.